

BIOMEDICA/BMC-smolvlm1-256M
0.3B • Updated • 2.61k • 2
This repository is publicly accessible, but you have to accept the conditions to access its files and content.
I understand that this dataset contains articles grouped under three licensing categories: Commercial Use Allowed (CC0, CC BY, CC BY-SA, CC BY-ND licenses), Non-Commercial Use Only (CC BY-NC, CC BY-NC-SA, CC BY-NC-ND licenses), and Other (no machine-readable Creative Commons license, no license, or a custom license). I acknowledge that each individual data point in the dataset specifies its corresponding license type, and I agree that it is my responsibility to verify compliance with the licensing terms before using any specific data point. I further agree to comply with the specific licensing terms of each group when using the dataset in accordance to what is established by the PubMed Central: PMC Open Acces Subset
Log in or Sign Up to review the conditions and access this dataset content.
Arxiv: Arxiv | Website: Biomedica | Training instructions: OpenCLIP | Tutorial: Google Colab
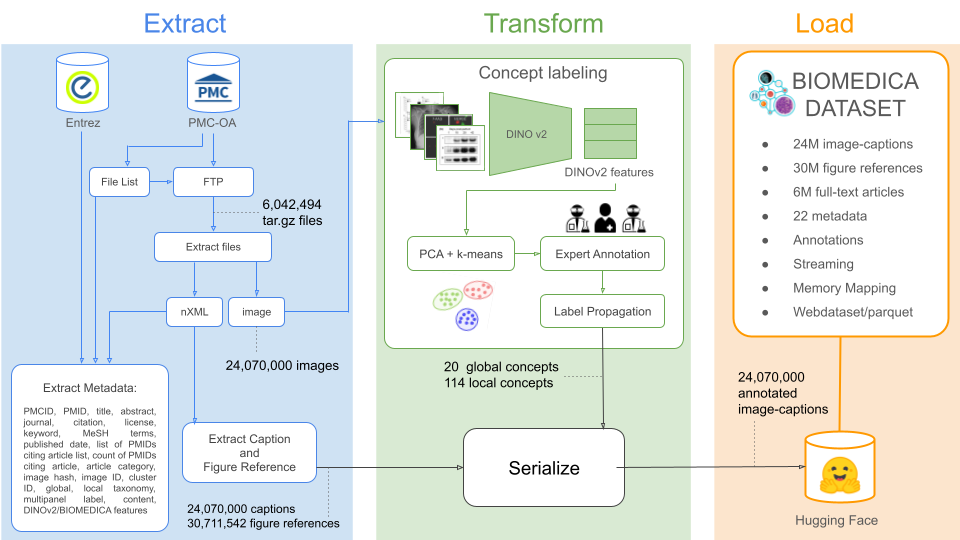
BIOMEDICA Dataset is a large-scale, deep-learning-ready biomedical dataset containing over 24M imagecaption pairs and 30M image-references from 6M unique open-source articles. Each data point is highly annotated with over 27 unique metadata fields, including article level information (e.g., license, publication title, date, PMID, keywords, MeSH terms) and coarse-grained image metadata (e.g., primary and secondary content labels and panel type) assigned via an unsupervised algorithm and human curation by a group of seven experts (clinicians and scientists).
BIOMEDIC\biomedica_webdataset is a serialized version of the BIOMEDICA dataset optimized for model development and formatted as a WebDataset for high-throughput streaming. This format provides 3x–10x higher I/O rates compared to random access memory.
This research was supported by NIH grants (NIH#P30AG066515 to JJN), the Chan Zuckerberg Initiative Neurodegeneration Challenge Pairs Pilot Project to SYL (2020-221724, 5022), the Wu Tsai Knight Initiative Innovation grant (#KIG 102) to SYL, Hoffman-Yee Research Grant to SYL, the Arc Institute Graduate Fellowship to AL, the Stanford Data Science Graduate Research Fellowship MW, and the Quad Fellowship to JB. SYL is a Chan Zuckerberg Biohub – San Francisco Investigator.
We thank Daniel van Strien, Matthew Carrigan, and Omar Sanseviero from Hugging Face for their invaluable assistance with data upload and design planning on the Hugging Face platform.
@inproceedings{lozano2025biomedica,
  title={Biomedica: An open biomedical image-caption archive, dataset, and vision-language models derived from scientific literature},
  author={Lozano, Alejandro and Sun, Min Woo and Burgess, James and Chen, Liangyu and Nirschl, Jeffrey J and Gu, Jeffrey and Lopez, Ivan and Aklilu, Josiah and Rau, Anita and Katzer, Austin Wolfgang and others},
  booktitle={2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  pages={19724--19735},
  year={2025},
  organization={IEEE}
}

@article{lozano2025large,
  title={A large-scale vision-language dataset derived from open scientific literature to advance biomedical generalist ai},
  author={Lozano, Alejandro and Sun, Min Woo and Burgess, James and Nirschl, Jeffrey J and Polzak, Christopher and Zhang, Yuhui and Chen, Liangyu and Gu, Jeffrey and Lopez, Ivan and Aklilu, Josiah and others},
  journal={arXiv preprint arXiv:2503.22727},
  year={2025}
}